Skip to content
Parishruthi Ganesh

    to navigate · to open · Esc to close

    Ph.D. Student, Computer Science and Software Engineering · Auburn University

    Parishruthi Ganesh

    I build and evaluate machine-learning systems for video understanding, language-model selection, and retrieval- and memory-grounded agents — with an emphasis on measurement that holds up: controlled comparisons, calibration, and honest reporting of what a benchmark can and cannot tell you.

    • Large Language Models
    • Model Evaluation & Benchmarking
    • Natural Language Processing
    • Computer Vision & Video Understanding
    • Retrieval-Augmented Generation
    • Agentic & Memory-Based Systems

    Auburn, Alabama, USA · parishruthig2gmail.com

    Portrait of Parishruthi Ganesh

    Currently working on

    Updated

    • Under review since 2026-01

      Interaction representations for early violence detection

      A controlled study isolating how much explicitly modelling person-to-person interaction contributes to early detection in video, currently under review at WACV.

      Read the write-up

    • Running experiments since 2026-03

      Model selection under statistical scrutiny

      Following the 41-model zero-shot evaluation, extending the protocol beyond single-label intent classification and treating benchmark saturation as a quantity to monitor rather than discover after the fact.

      Read the write-up

    • Building since 2024-01

      Faculty expertise retrieval at institutional scale

      Extending the AUSME retrieval pipeline over roughly 25,000 papers toward a deployment that lets faculty and research groups query publications in natural language.

      Read the write-up

    • Building since 2024-06

      CIM4DE data models for digital engineering

      Building out entity relationships, classification hierarchies and automated data-quality classification inside the DEMA desktop platform.

      Read the write-up

    Research

    Four questions the work keeps returning to

    All research themes →
    • Language-Model Evaluation and Model Selection

      When a practitioner has to choose one open-weight language model out of dozens for a classification task, what evidence actually supports that choice — and how much of the apparent difference between leading models is real rather than noise?

      Zero-shot classification Open-weight LLMs Confidence calibration Statistical significance
    • Video Understanding and Early Detection

      How much of the performance of a video model on early detection tasks comes from explicitly representing the interaction between people, rather than from appearance and motion features that any strong backbone already captures?

      Video understanding Interaction representations Early event detection Ablation study
    • Retrieval-Augmented Generation over Scholarly Corpora

      What does a retrieval pipeline over a large, heterogeneous corpus of research papers need in order to answer expertise questions — "who here works on this, and what have they actually shown?" — rather than merely returning topically similar text?

      Retrieval-augmented generation LangGraph Semantic retrieval Document parsing
    • Agentic and Memory-Based Systems

      If an agent's memory is a context window, it forgets on restart and on handoff. What specifically does an operational agent need to persist — and what changes when memory becomes a queryable, transactional store instead?

      Agentic systems Vector retrieval Episodic and semantic memory Human-in-the-loop approval

    Publications

    Selected papers

    All publications →
    Preprint 2026 · arXiv preprint

    Selecting Open-Weight Language Models for Zero-Shot Intent Classification: A Systematic Evaluation of 41 Models

    Parishruthi Ganesh , Gerry Dozier , Cheryl Seals

    Preprint available on arXiv; submitted to AAAI.

    A systematic zero-shot evaluation of 41 open-weight language models spanning 15 families and the 135M–9B parameter range, across eight English single-label intent-classification datasets covering standard benchmarks, a large-scale voice-assistant corpus, and production-derived e-commerce datasets. Beyond exact-match accuracy the study analyses confidence calibration, robustness to realistic input perturbations, statistical reliability of model rankings, deployment efficiency, and benchmark saturation. Results show that instruction-tuned 3B models can outperform several evaluated 7B base models, that differences among leading models on MASSIVE are statistically indistinguishable under pairwise McNemar tests, and that widely used benchmarks such as SNIPS have become saturated and no longer meaningfully discriminate among current open-weight models.
    Preprint 2026 · arXiv preprint

    What Do Interaction Representations Actually Measure? Pre-Event Separability in Weakly-Supervised Violence Detection

    Parishruthi Ganesh

    Preprint available on arXiv; submitted to WACV. arXiv posting is not peer review, so no acceptance is claimed and no venue year is asserted.

    Articulated human pose provides detailed body-configuration information beyond coarse spatial relationships, but whether this detail yields greater discriminative information when the downstream pipeline is held fixed remains unclear. We examine this through early violence detection. Holding the tracker, temporal head, supervision, folds, and evaluation fixed, we compare five interaction representations spanning coarse bounding-box geometry, a matched handcrafted pose analogue, enriched pose descriptors, and a matched-capacity encoder learned from raw joints, under video-level evaluation with cluster-bootstrap intervals. No pose-based representation outperforms coarse geometry, though with fifteen anomalous videos this subset cannot rule out small effects. Extending the pipeline to frozen visual encoders, and repeating the comparison on XD-Violence (137 anomalous videos, nine times our UCF- Crime sample), person-crop appearance and whole-frame context both exceed geometry by a wide margin, yet context matches appearance on UCF- Crime and exceeds it on the larger split: cropping to the interacting people yields no advantage over encoding the whole frame. This prompts a direct test of what the benchmark measures. Scoring anomalous videos using only frames preceding the annotated onset, under a control removing sequence length as a cue, retains 39-91% of above-chance separation on both benchmarks, including for seven hand-designed geometric channels. Inspection of the tightest pre-onset windows identifies concrete provenance artifacts: editorial title cards and platform watermarks absent from the surveillance footage supplying the normal class. Video-level AUC here is thus a composite of event evidence and pre-event source cues, a shared source of discrimination that can obscure differences between representations. The diagnostic requires only annotations these benchmarks already ship.

    Projects

    Featured work

    All projects →
    Featured Completed 2026

    Zero-Shot Intent Classification Benchmark

    A systematic zero-shot evaluation of 41 open-weight language models across eight intent-classification datasets.

    LLM Evaluation

    Python · Hugging Face Transformers · PyTorch · vLLM · Statistical Testing

    Featured Prototype 2026

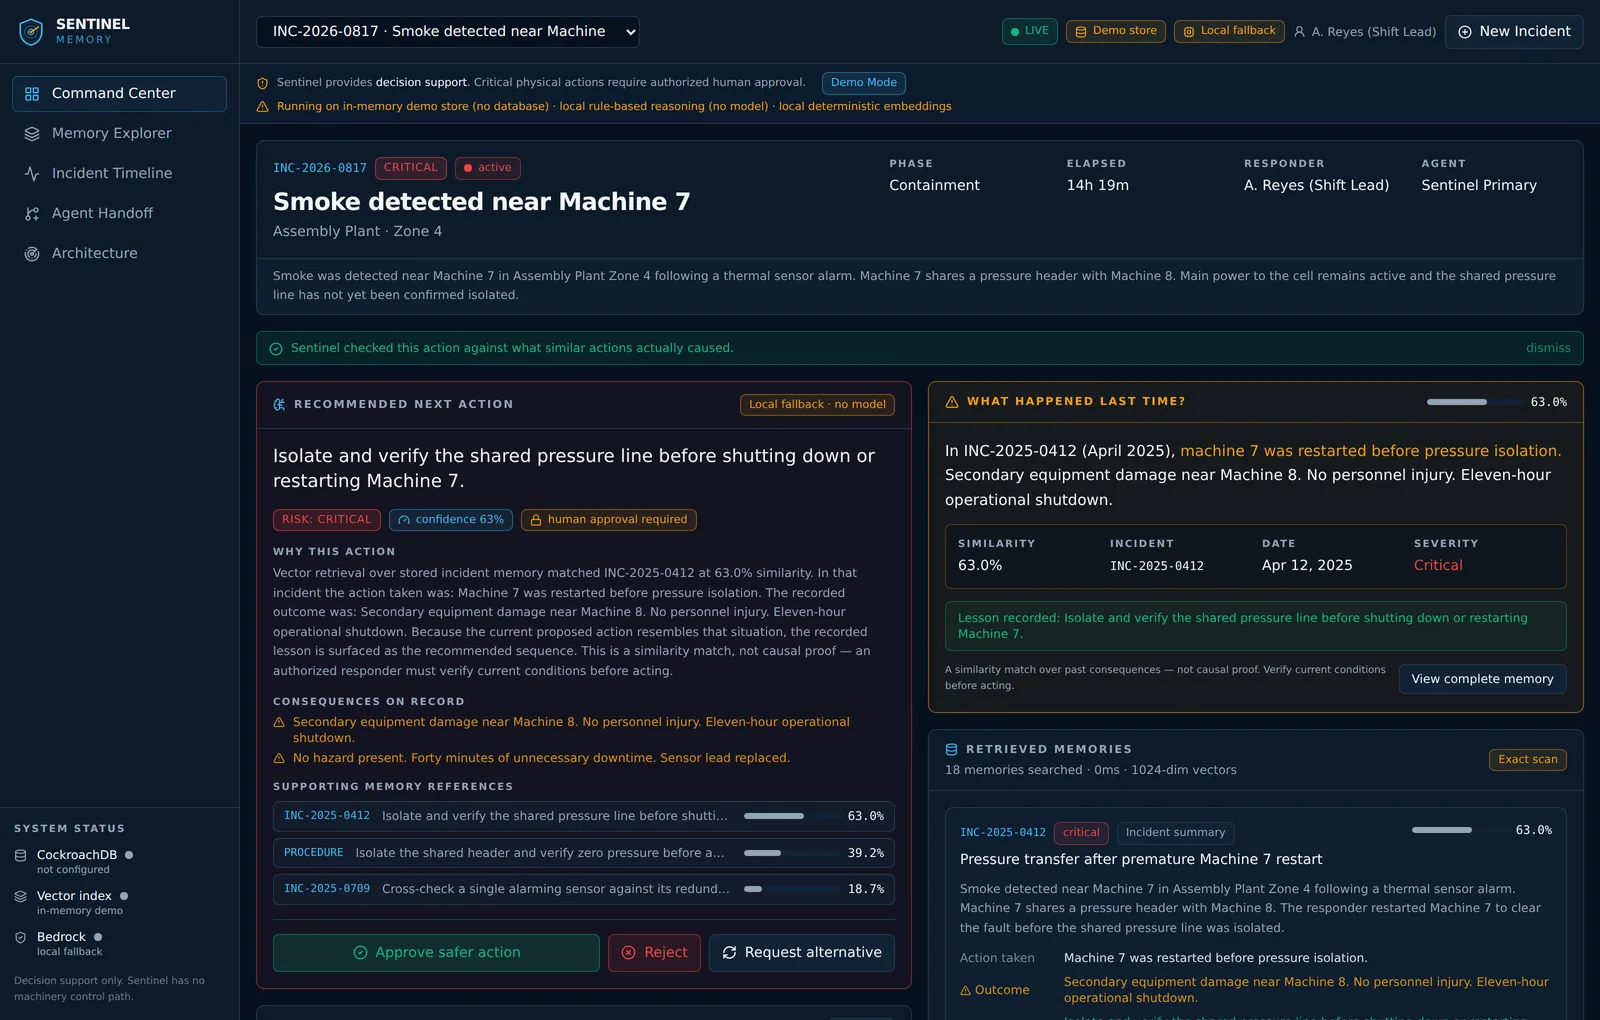
    Sentinel Memory

    An incident-response agent whose memory is a transactional database rather than a context window — it remembers consequences, not conversations.

    Agentic Memory

    TypeScript · Next.js · React 19 · Tailwind CSS · CockroachDB · Amazon Bedrock · +3

    Featured Prototype 2026

    AstraNova

    An AI trading copilot for India's options traders — live market data, AI-scored signals, broker execution and a Gemini-powered assistant.

    Applied AI & Data

    Python · Google Gemini · Angel One API · Real-time Market Data

    Hackathons

    Recent builds

    All hackathons →

    GitHub

    Recent repository activity

    All repositories →
    • The source of this site: an Astro + TypeScript + Tailwind portfolio with Zod-validated structured content, a GitHub synchronisation pipeline and a `portfolio` CLI for adding papers, projects and hackathons.

      Last push 15 days ago

    • An incident-response agent whose memory is a transactional database rather than a context window. Retrieval over CockroachDB's distributed vector index surfaces what a proposed action cost during a previous incident, with the incident code, date and damage attached; approval commits four writes in one transaction. 94 tests, none requiring a live cluster.

      Last push 16 days ago

    • Graph-based detection of circular trading rings in iron-dealer invoice data: cycle detection over a multi-graph representation feeds a per-node suspicion score, Node2Vec embeddings, and DBSCAN clustering to isolate dense regions of anomalous trading behaviour.

      Last push 10 months ago

    • A small vanilla-JavaScript task list. Early web practice, listed for completeness under coursework and learning labs.

      Last push last year